|
Hello, I am a master's student in Computer Science and Engineering at the University of California, San Diego. My research focuses on evaluating and improving large language models and LLM agents, including factuality, tool use and benchmark reliability. I am currently supervised by Professor Jingbo Shang on how LLM agents gather and use evidence when exploring unfamiliar computational systems. I earned my Bachelor of Engineering in Computer Science and Engineering from The Chinese University of Hong Kong, where I completed the ELITE stream, and graduated with First Class Honours and a minor in Mathematics. I was very fortunate to have been advised by Professor Wenxuan Wang. Email / Github / Google Scholar / CV / linkedin |
|
|
|
|
University of California, San Diego, La Jolla, CA Sep 2026 - Jun 2028 (Expected) Master of Science, Department of Computer Science and Engineering Computer Science |
|
The Chinese University of Hong Kong, Hong Kong Aug 2022 - Jul 2026 Bachelor of Engineering, Department of Computer Science and Engineering Artificial Intelligence – Systems & Technologies, First Class Honours, ELITE Stream, Minor in Mathematics |
|
|
|
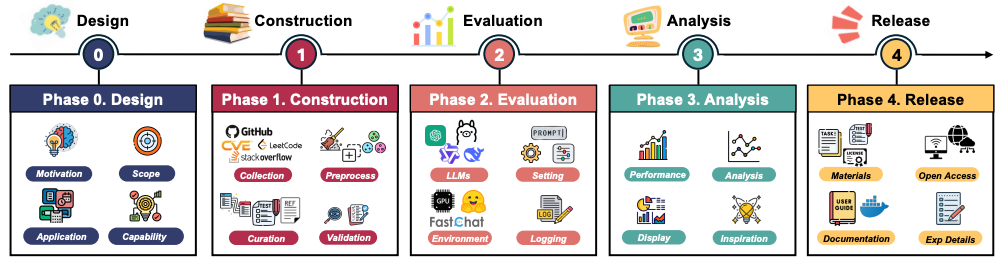
Jialun Cao, Yuk-Kit Chan*, Zixuan Ling*, Wenxuan Wang, Shuqing Li, Mingwei Liu, Ruixi Qiao, Yuting Han, Chaozheng Wang, Boxi Yu, Pinjia He, Shuai Wang, Zibin Zheng, Michael R. Lyu, Shing-Chi Cheung ICML, 2026 arXiv | ICML We conducted a decade-scale survey of 672 code benchmarks, found a growing awareness gap in rigorous benchmark practice, and respond by proposing HOW2BENCH |
|
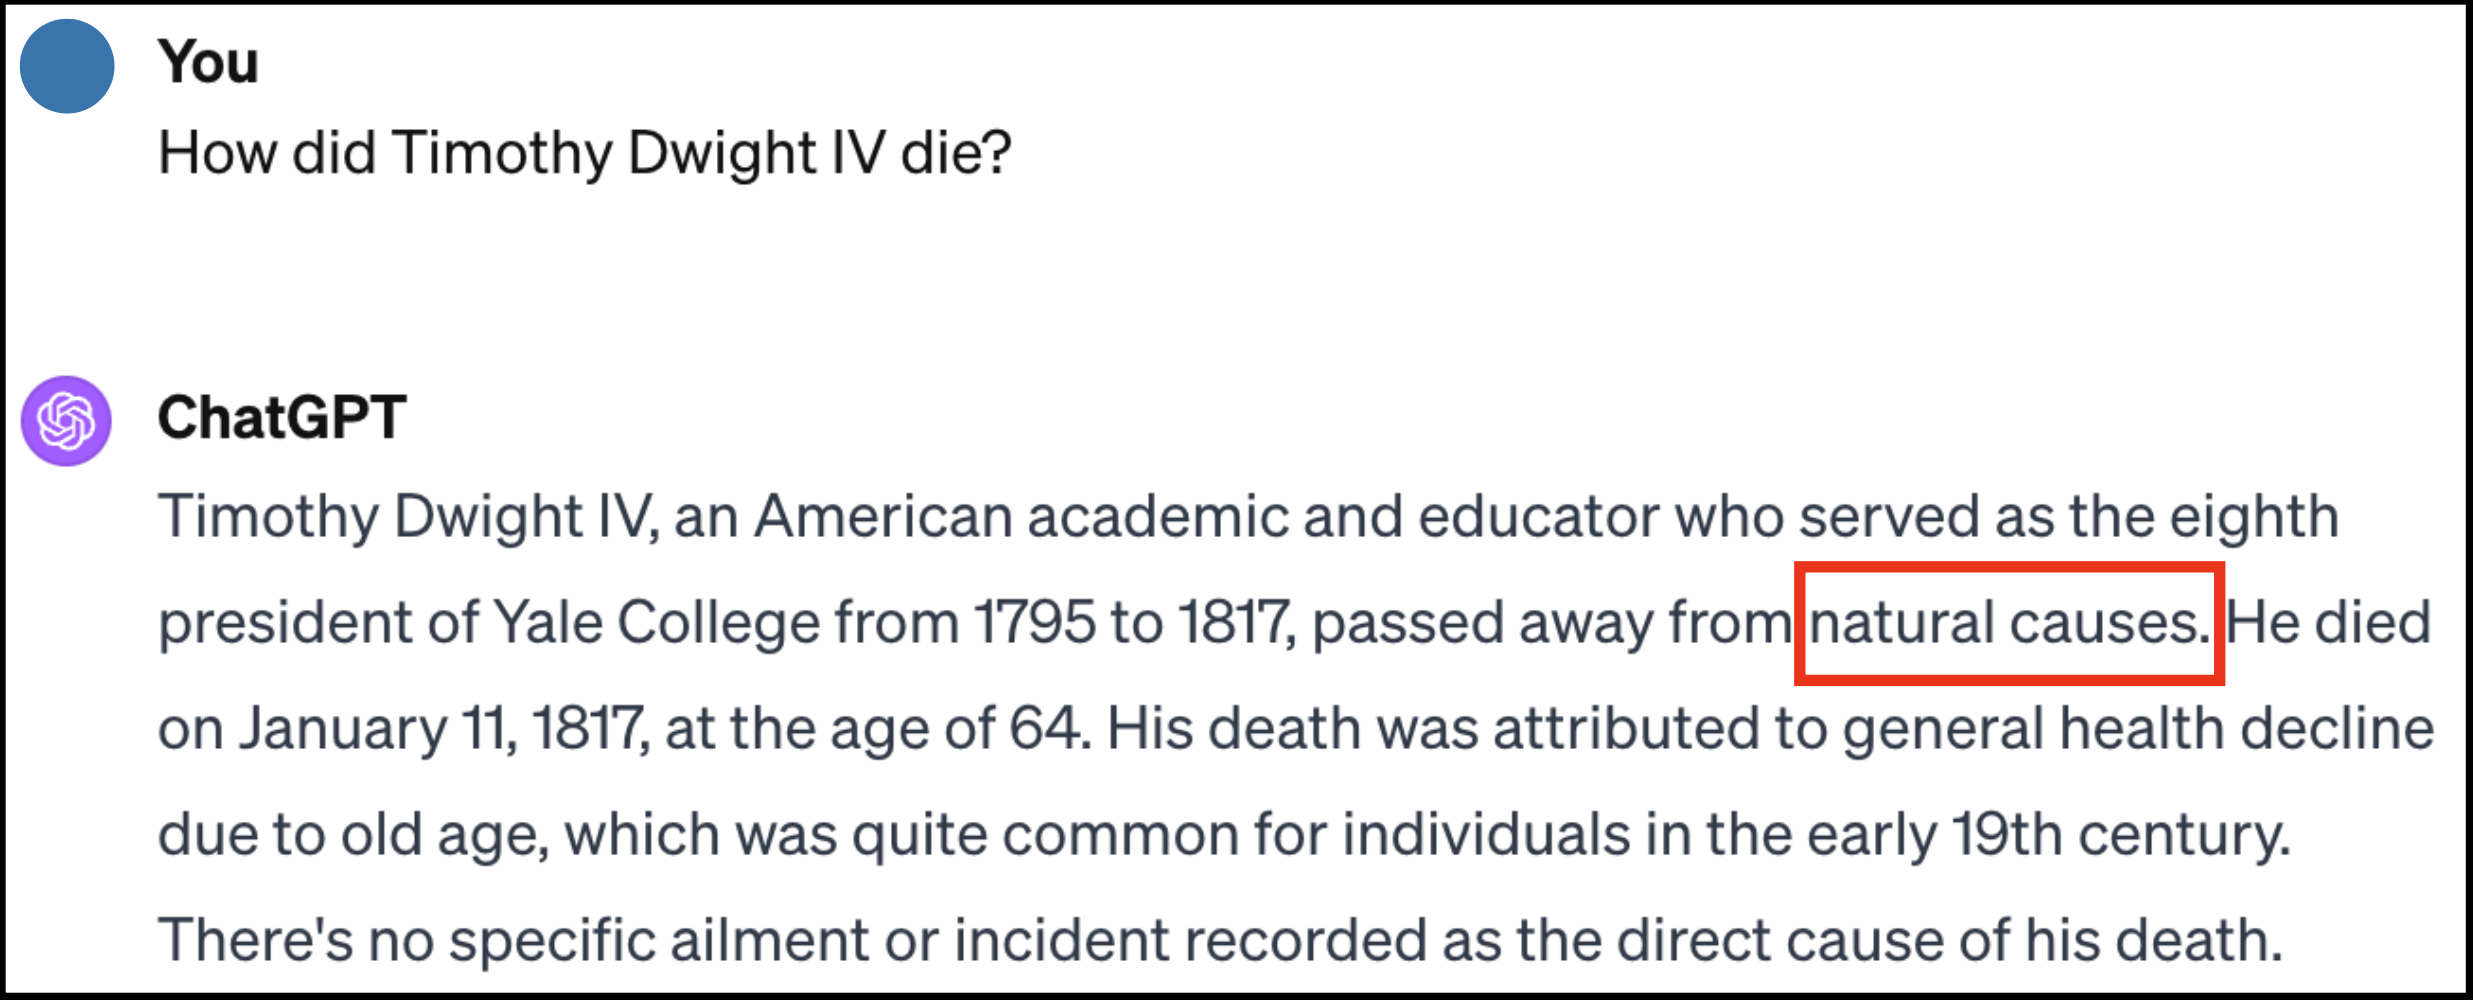
Wenxuan Wang, Yuk-Kit Chan*, Zixuan Ling*, Juluan Shi*, Youliang Yuan, Jen-tse Huang, Yifei Zhang, Wenxiang Jiao, Zhaopeng Tu, Michael R. Lyu Findings of ACL, 2026 arXiv | ACL | Github We introduce HalluHunter, a fully automated knowledge-graph framework that generates single- and multi-hop factuality questions and adaptively targets LLM weaknesses |
|
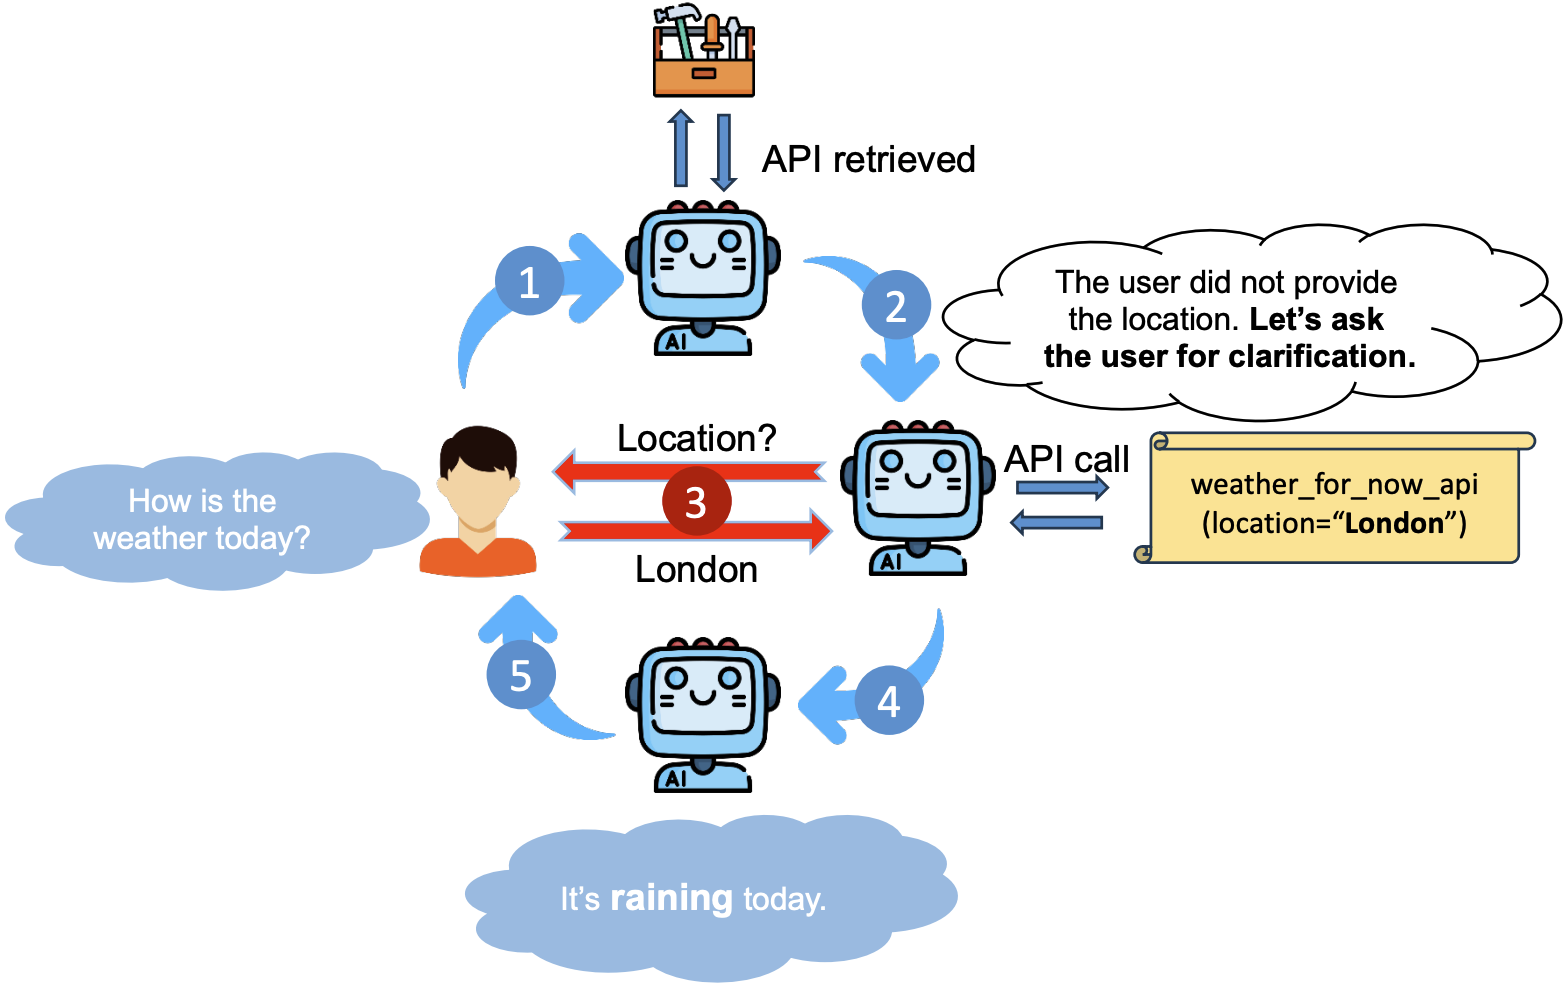
Wenxuan Wang, Juluan Shi*, Zixuan Ling*, Yuk-Kit Chan*, Chaozheng Wang, Cheryl Lee, Youliang Yuan, Jen-tse Huang, Wenxiang Jiao, and Michael R. Lyu EMNLP, 2025 arXiv | EMNLP | Github We study tool-use under imperfect user instructions by analyzing real queries and introducing Noisy ToolBench, showing LLMs often hallucinate missed arguments; we then propose Ask-when-Needed (AwN) and an automated ToolEvaluator that improve tool-use accuracy over existing methods. |
|
|
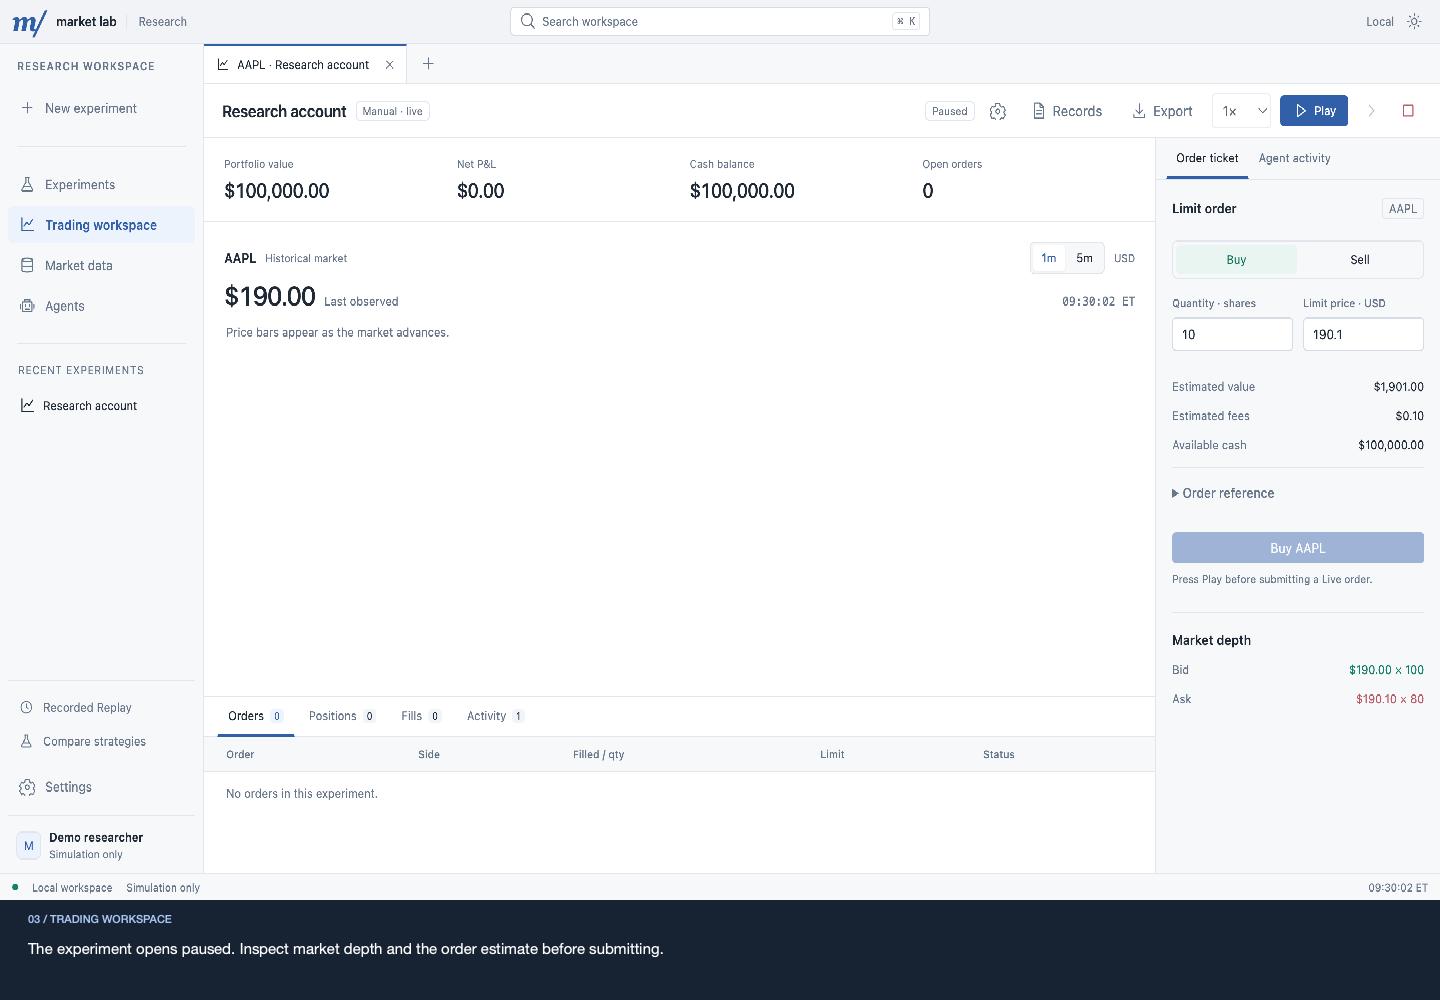
|
Sole developer Open source, v1.0.0, 2026 Website | Github | PyPI A local platform for building LLM trading agents and testing them against human, rule-based and neural-network baselines on historical market data, with a C++ market engine, replayable records and statistical evaluation. |
|
Last updated Nov 2026.
|